
[ capabilities ]
What An Evaluation And Monitoring Setup Covers
You can't fix what you can't measure. We give your team a clear view of how the agent performs, and a way to keep it that way.

Agent & LLM audit
We review your prompts, tools, data sources and current failures to see where the agent goes wrong and why.

Evaluation test sets
We build test cases from your real use cases and edge cases, so every answer and task can be scored the same way each time.

Accuracy & task scoring
We score answers for correctness, grounding in your data, and whether the agent actually finished the task it was given.

Guardrails & safety checks
We test for prompt injection, off-topic replies, data leaks and unsafe actions, then add guardrails where they're needed.

Live monitoring & alerts
We trace every run in production and alert your team when error rates, costs or response times move the wrong way.

Regression testing for changes
Before you switch models or edit a prompt, the test set runs again, so an improvement in one place doesn't break another.



[ process ]
How We Evaluate And Monitor Your Agent
We measure first, fix second, and leave you with tests and dashboards your team can keep running without us.

[step 01]
Agent review
We learn what the agent is meant to do, how it's built, and where users or your team see it fail.

[step 01]
Test set & scoring
We write test cases and scoring rules with you, then run them to get a baseline you can trust.

[step 01]
Fixes & guardrails
We fix the biggest failure causes in prompts, retrieval or tools, and add guardrails for risky actions.

[step 01]
Monitoring & handover
We set up tracing, dashboards and alerts, then walk your team through running the tests themselves.
[ stacks ]
The Tools We Use To Test And Watch AI
We work with the models and frameworks you already use, and add tracing and monitoring that fits your stack rather than replacing it.


[ case studies ]
Case studies


AI & ML
[
Talkie
]
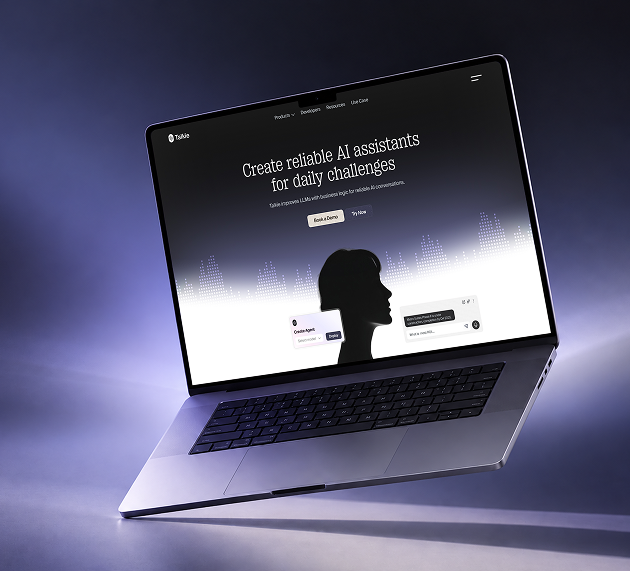
AI assistant marketing site
AI and automation build · 4-week engagement period · Demo-led launch plan
[ The challenge ]
Talkie sold a technical product that buyers struggled to picture, so the team needed a site that showed voice and chat assistants at work and earned trust before any sales call.
Next.js
Typescript
Tailwind CSS
Node.js
PostGreSQL
[ What we built ]
Interactive voice and chat demos sit beside integration maps and live impact figures, all linked to a short form for free trials and demo bookings.
2.6×
Demo bookings
38%
Trial sign-up lift
1.4s
Page load time
SaaS website · Brand, UI/UX & development
[ projects ]
AI And Automation Work We've Delivered


FLUXPILOT
Website
Enterprise AI
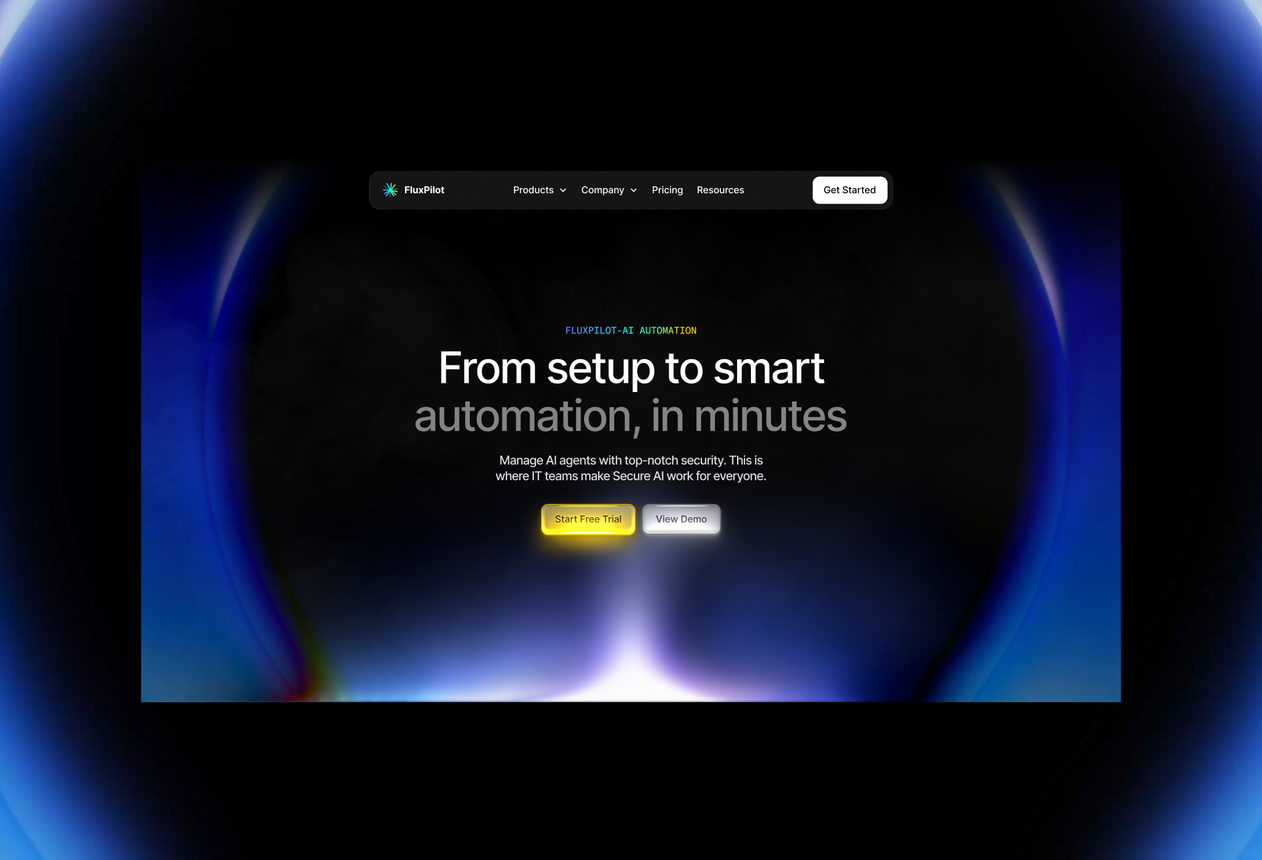
Agentic workflows that IT teams can trust
Enterprise AI has to be safe before it is smart. For FluxPilot, we automated workflow logic with security, governance, and human-approval steps, then connected it to the tools teams already use.

NEXORA
Website
AI Productivity
Writing, images, and automation in one AI suite
Building four AI tools under one roof is hard. We connected the models, custom personas, file uploads, and saved prompts so Nexora runs smoothly from the very first free trial.

INKORA
Website
AI Writing
AI writing tools tuned for blogs and SEO
Inkora needed content that comes out fast and reads well in many languages. In this case, we wired the AI models into chat-style tools for blogs, SEO, and articles, and tracked usage so growth stays visible.
DEEPVISION
WebApp
AI Creative
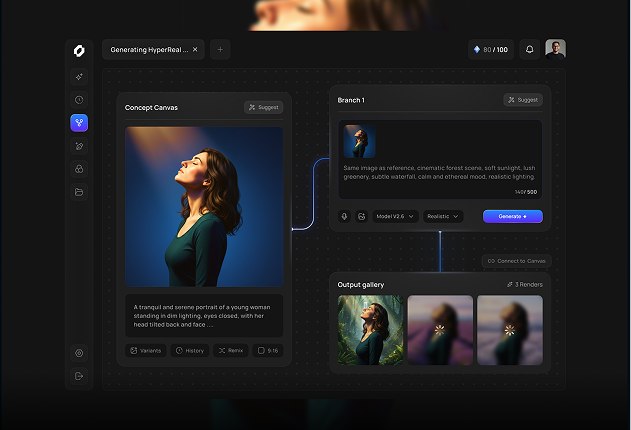
A node canvas that branches ideas into renders
We built the AI engine behind DeepVision, from prompt branching to model selection and style controls. Renders land in the gallery fast, and remix and history tools make every experiment easy to trace back.
[ transformation ]
The Rebuild, Not The Pitch
Projects often begin with damage control: the audit, the fix, and the aftermath.
A dedicated 4-person pod
Designer, engineers and QA, all on your product.
One team, two platforms
iOS + Android, one team, one codebase.
Crash-free at scale
99.2% stability across 1.8M live users.
What clients actually say
Feedback from founders we've shipped with.
Direct speak with the engineer
Saiful replies directly, no manager in the loop.
Built in Dhaka, shipped globally
Live in 9+ countries across four continents.
[ testimonial ]
What It's Like Working With Us
Sofia Gouveia @ Esdiac
Design Director
We relied on them to build our online store with AI-enhanced features that improve customer experience.
Working with Dev Monks on our ESDIAC app and group websites was an excellent experience. They were patient, attentive to feedback, and delivered clean, consistent, high-quality work. We're proud of the results and happy to continue our long-term partnership with them.

Anika @ Coin Pulse
Founder
Their team truly understood our vision and brought it to life through a stunning digital identity.
Dev Monks is a professional, reliable partner for end-to-end product builds. From clean, modern designs to seamless development, they exceeded my expectations. I couldn't be happier with the collaboration!
Austin @ Clarity LLC
CEO
Working with Dev Monks completely changed how we approached building our app website scratch.
I've worked with Design Monks on three websites, and they've been nothing but exceptional. Their design is top-notch, development is reliable, and communication is always smooth. They quickly act on feedback and deliver exactly what I need. For me, they're a 10/10 partner for all things design and development.
Ted Nash @ Yenex
Founder & CEO
I never expected building a complex platform to feel this easy and smooth.
I've had the pleasure of collaborating with Dev Monks for a while now on my new project. They're lightning-quick in addressing any questions or feedback I have, and they consistently go the extra mile to make sure I'm thrilled with the final outcome. I wholeheartedly endorse them


[ faq ]
Questions You'd Ask Before Signing Off

What is an AI agent evaluation?

It's a repeatable set of tests that checks whether your agent gives correct answers and completes its tasks. Each test has a clear pass or fail rule, so you can compare versions instead of guessing.
Can you evaluate an agent another team built?
Yes. We only need access to the agent, its prompts and tools, and some example conversations or tasks. We can sign an NDA before we start.
Do we need to change our model or framework?
No. We test what you have. If a different model would do better or cost less, we show you the test results so you can decide. For cost-focused work, see AI Cost Optimization.
How is this different from your AI Code Security Audit?
The AI Code Security Audit reviews your code for vulnerabilities. This service tests how the AI itself behaves: its answers, its actions, and how it handles bad input.
What do we keep at the end?
Your test set, scoring rules, monitoring dashboards and alerts, plus a short guide so your team can run the tests before every release.


[ start project ]
Not Sure How Often Your AI Agent Gets It Wrong?
Send us a few conversations or tasks where it struggled. We'll tell you what we'd test first and what a monitoring setup would look like.
Typical range
$15,000 – $80,000
~/devmonks/stack.ts

Dual-store launch included

Fixed, transparent scope
Your ideas deserve more than prototypes. Partner with Dev Monks and bring scalable, reliable, and AI-enhanced products to life today.


